Distributed Data on AWS: Transactions, Aurora Failover Behavior, DynamoDB Partitions, and Shard-Like Aurora Limitless
Quick summary: July 2026 field note: Aurora failover windows still force app timeouts above tens of seconds; DynamoDB hot partitions and short transactions remain the scaling levers, with a partition-math worksheet you can reproduce.
Key Takeaways
- This note ties OLTP transactions on RDS/Aurora to partitioned access patterns on DynamoDB and shard-like scaling with Aurora Limitless
- Failure mode: ORM chatter opens transactions across multiple user requests, pinning connections and bloating undo volume, and p95 query time climbs while CPU looks fine
- What broke: A service using a 10s global HTTP client timeout talked to RDS through a proxy that surfaced failover as connection reset
- DynamoDB partitions and hot keys DynamoDB scales partitions, but your access patterns still dictate heat
- Single-key fan-in (global counters, one ) becomes a physics problem; see design guidance in single-table DynamoDB patterns
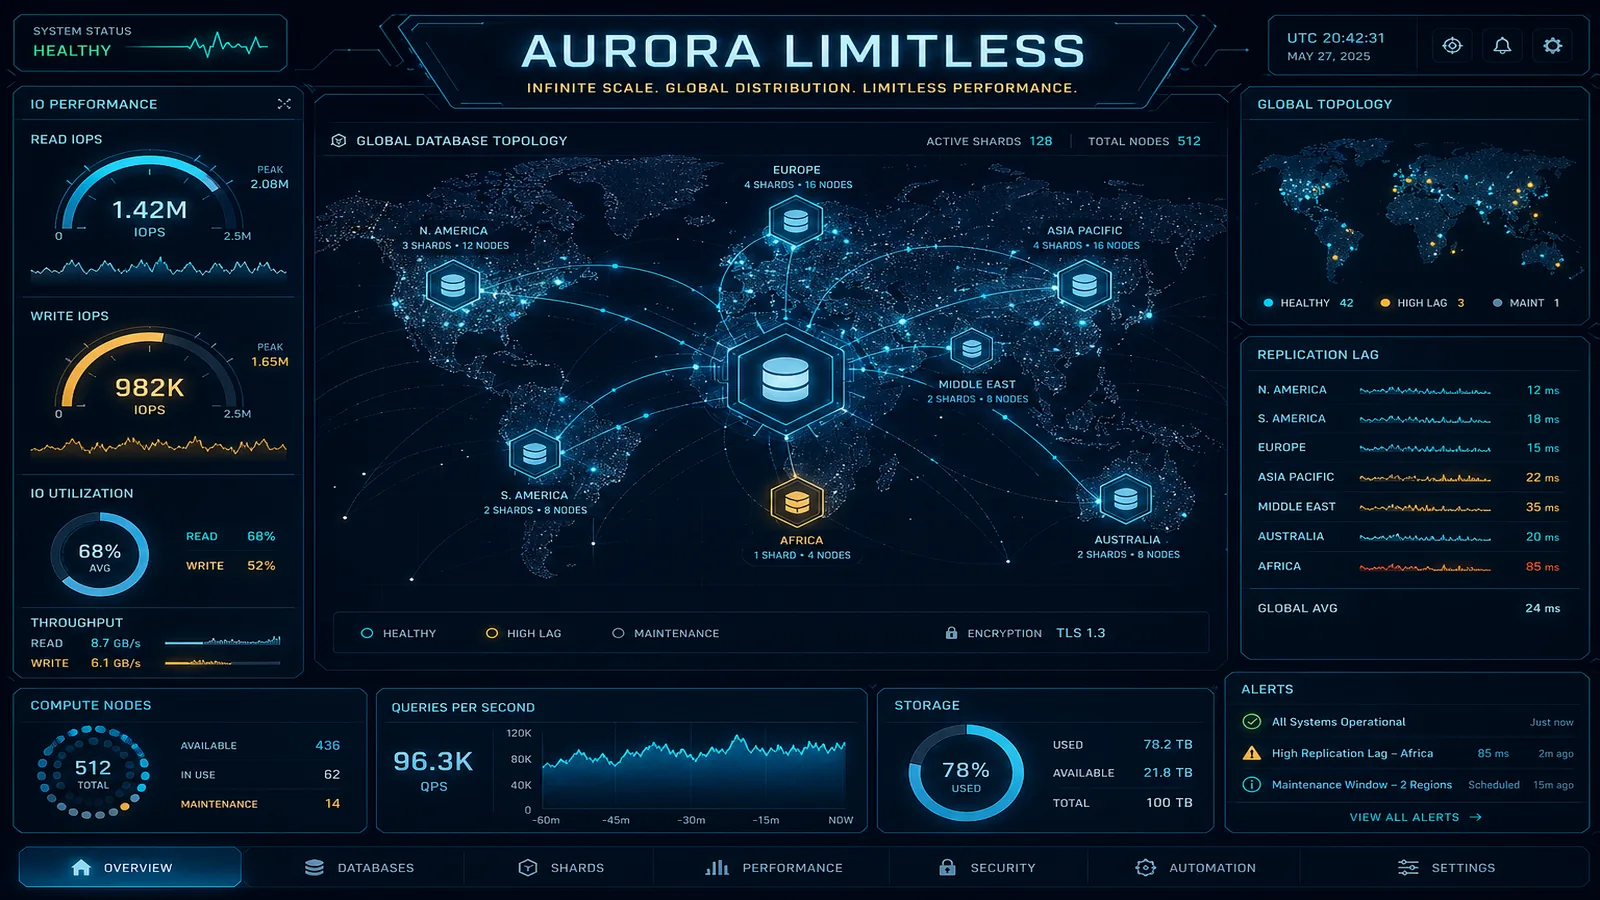
Table of Contents
On July 19, 2026, “distributed systems on AWS” still comes down to three buyer problems: partial failure visibility, data plane timeout alignment, and write skew when you pretend relational transactions stretch infinitely across managed services. The May field note holds; the numbers below are still the ones that show up in architecture reviews.
This note ties OLTP transactions on RDS/Aurora to partitioned access patterns on DynamoDB and shard-like scaling with Aurora Limitless. You cannot SD-WAN the CAP theorem away.
Transactions: keep them short
RDS/Aurora transactions buy ACID within the instance (with the isolation level you actually configured, not the default you forgot).
Failure mode: ORM chatter opens transactions across multiple user requests, pinning connections and bloating undo volume, and p95 query time climbs while CPU looks fine.
Pair operational tuning with RDS performance best practices.
Aurora failover is not zero downtime
Aurora promotes a new writer after failures or planned failovers. Application stacks must:
- Retry DNS / endpoint resolution with backoff (drivers differ).
- Set TCP and JDBC timeouts above expected failover windows (historically often on the order of tens of seconds; validate with your version and observe in drills rather than copying a number).
DynamoDB partitions and hot keys
DynamoDB scales partitions, but your access patterns still dictate heat. Single-key fan-in (global counters, one tenantId) becomes a physics problem; see design guidance in single-table DynamoDB patterns.
Aurora Limitless as a shard-like option
For the AWS-native horizontal OLTP story, read Amazon Aurora Limitless Database before hiring a sharding committee, then decide whether your workload truly demands that operational surface.
MongoDB when relational models fit poorly
Some domains map cleanly to documents and aggregation pipelines. Evaluate costs and ops on AWS in MongoDB scalable cost guidance.
Streaming partitions work the same way
Kinesis and MSK partition keys behave like DynamoDB hot keys: ordering and throughput guarantees depend on the key you pick. If you ingest ordered events, our Kinesis vs MSK guide helps pick the right streaming plane before mirroring partition mistakes into two systems.
What this post does not cover
- Analytics warehouses (Redshift, Iceberg lakehouses): different latency and consistency contracts entirely.
- Multi-region active-active data planes: start from multi-region cost design before promising caps.
If you only do one thing
Plot p99 transaction duration and connection pool utilization on one chart. If they diverge, you are hiding lock contention behind average CPU.
What to do this week
- Run a documented failover drill in staging; capture DNS/TTL and client retry behavior, not just database health.
- List top 20 DynamoDB access patterns; underline any key with >20% of consumed capacity.
- Revisit ORM transaction boundaries; grep
@Transactional(or equivalents) crossing network I/O.
If messaging absorbs overloaded writes, link to event-driven boundaries.
Frequently asked questions
When should we avoid distributed transactions across RDS and DynamoDB?
What breaks naive sharding logic?
Is Aurora Limitless the default for every OLTP workload?
What is wrong with long open transactions on RDS under load?
When does MongoDB on AWS still make sense?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.