EC2 M9g and M9gd (Graviton5) GA: When to Move Off M8g — and When to Wait
Quick summary: On June 10, 2026 AWS made M9g/M9gd on Graviton5 generally available: up to 25% more compute vs M8g, and 35% faster for web and ML per AWS. Field guide to M9g vs M9gd, a canary checklist, RI traps, and agentic-AI fit. The compute-optimized siblings C9g/C9gd went GA June 30.
Key Takeaways
- On June 10, 2026 AWS made M9g/M9gd on Graviton5 generally available: up to 25% more compute vs M8g, and 35% faster for web and ML per AWS
- Field guide to M9g vs M9gd, a canary checklist, RI traps, and agentic-AI fit
- The compute-optimized siblings C9g/C9gd went GA June 30
- On June 10, 2026, AWS announced general availability of Amazon EC2 M9g and M9gd instances, the first general-purpose shapes powered by AWS Graviton5
- AWS claims up to 25% better compute versus Graviton4-based M8g/M8gd, up to 30% faster databases, and up to 35% faster web applications and machine learning
Table of Contents
On June 10, 2026, AWS announced general availability of Amazon EC2 M9g and M9gd instances, the first general-purpose shapes powered by AWS Graviton5. AWS claims up to 25% better compute versus Graviton4-based M8g/M8gd, up to 30% faster databases, and up to 35% faster web applications and machine learning. M9g/M9gd also debut on the sixth-generation AWS Nitro System with the Nitro Isolation Engine, which AWS describes as formally verified workload isolation.
If your fleet already runs on M8g, this is not a fire drill, but you should stop buying new M8g commitments until you have canary data. If you are still on x86 m7i/c7i, Graviton5 widens the price-performance gap further. Start with our Graviton cost optimization guide before jumping generations.
Sibling launch, June 30, 2026: AWS made C9g and C9gd generally available. They are compute-optimized Graviton5 instances with up to 25% higher performance per vCPU vs C8g. Stay on M9g for balanced app/API fleets; switch the canary to C9g (or C9gd for local NVMe scratch) when the workload is CPU-bound (batch, encode, HPC, CPU inference). Use the C8g→C9g canary checklist.
This post covers what changed, how M9g differs from M9gd, where agentic AI fits, what breaks in real migrations, and a Monday-morning canary plan.
What AWS shipped on June 10, 2026
| Instance | Processor | Local storage | AWS-positioned workloads |
|---|---|---|---|
| M9g | Graviton5 | EBS root + volumes | App servers, microservices, gaming, caching, containers, agentic AI orchestration |
| M9gd | Graviton5 | NVMe instance SSD | Media processing, batch/log processing, scratch caches, temp files |
Regions (GA): US East (N. Virginia), US East (Ohio), US West (Oregon), EU (Frankfurt).
Purchase options: On-Demand, Spot, Savings Plans, Reserved Instances, Dedicated Instances, Dedicated Hosts, the same menu as M8g.
Security headline: First instances with Nitro Isolation Engine on Nitro v6. For regulated teams, add this to your next architecture review deck. It rarely changes instance sizing decisions.
How to read the performance claims
AWS publishes generation-over-generation uplifts:
- +25% compute vs M8g/M8gd
- +30% databases
- +35% web apps and ML
Those numbers are AWS lab benchmarks, not your invoice. Map them to your telemetry:
| Your signal | What Graviton5 likely improves | What it will not fix |
|---|---|---|
High CPUUtilization, low I/O wait | M9g size-for-size or same size + headroom | None |
| Aurora/Redis latency dominates | Modest p95 win unless CPU-bound on DB client | Move data tier or cache layer |
EBS VolumeQueueLength saturated | Maybe 0% on M9g; evaluate M9gd | Wrong sub-family |
| Agent tool-calling + JSON APIs on same host | Better $/orchestration step | Still need right-sizing vs GPU/Trainium for big models |
Opinionated take: For new general-purpose Graviton fleets in a GA Region, default launch template to M9g after a 10% canary, and skip the big-bang ASG replace. For memory-heavy OLTP, benchmark r9g when AWS ships it, and do not force M9g where r8g is the right economic fit. For x86 with 9+ months of RI left, schedule the M9g evaluation for RI expiry, because ripping RIs out early rarely pencils out.
M9g vs M9gd: pick the sub-family before the size
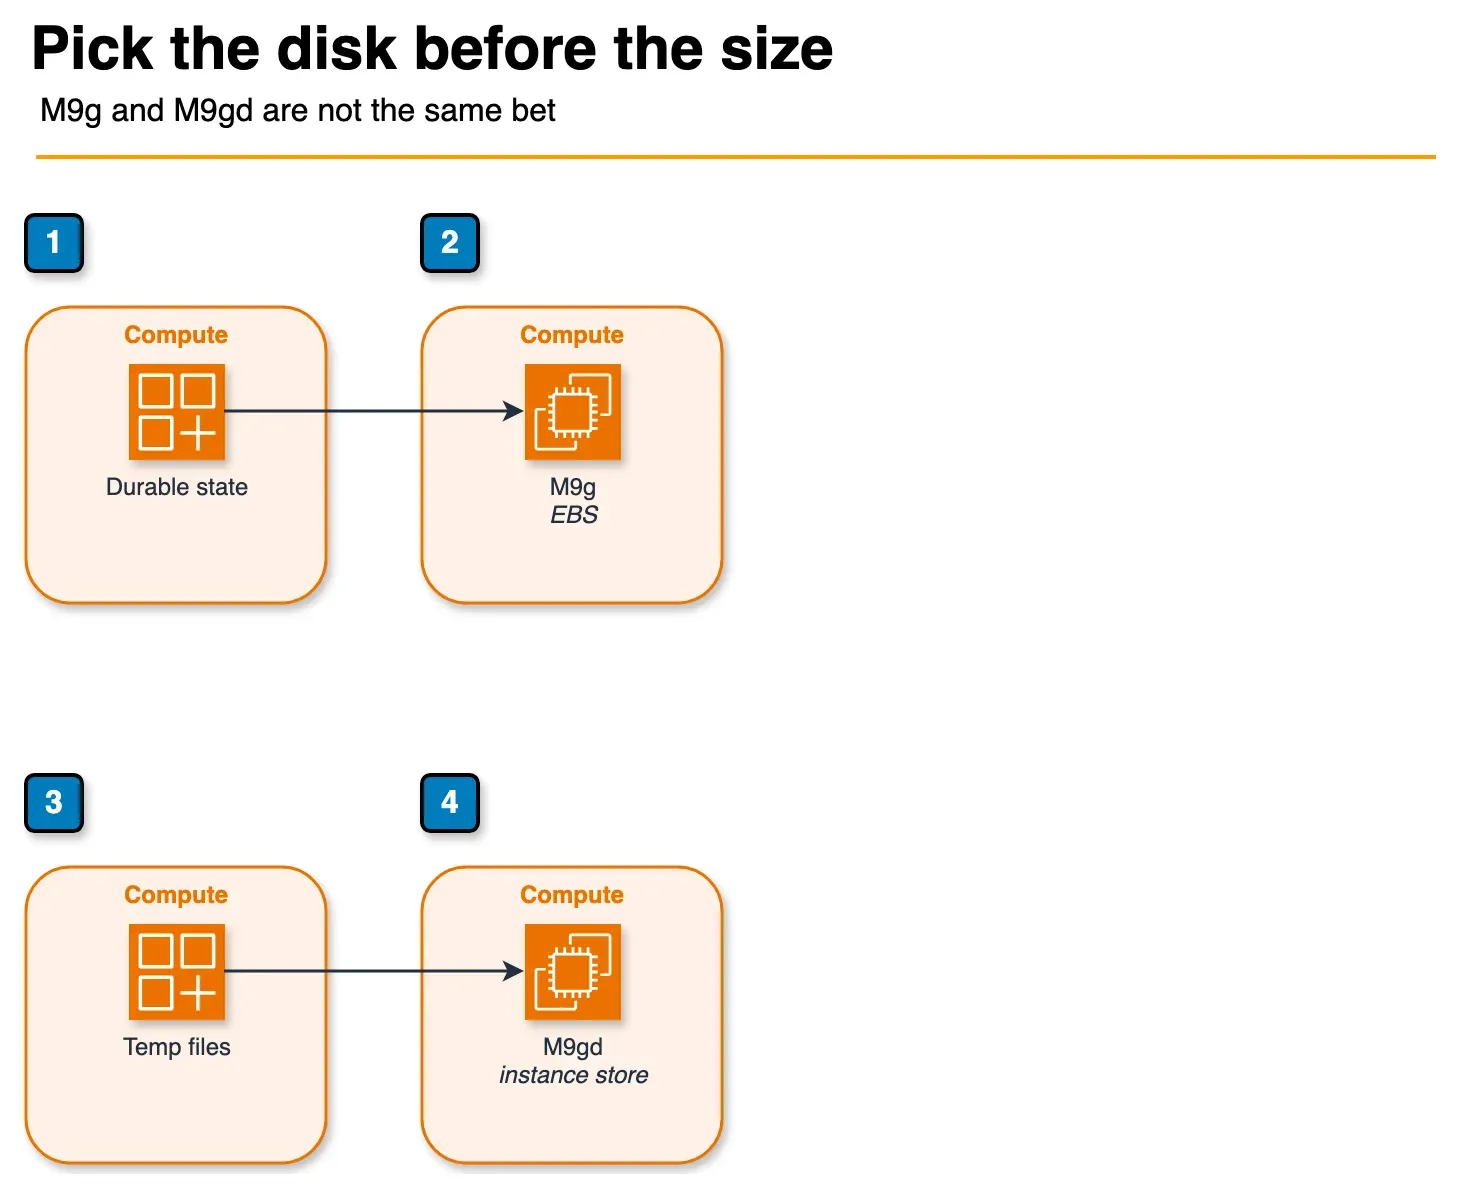
Figure: the sub-family choice in the article. Durable state stays on EBS with M9g. Large temporary files use M9gd instance store, and that data is gone when the instance stops. The pilot’s instance size and the speed figure stay in the article. Open the draw.io source.
M9g when:
- Containers or AMIs store durable state on EBS/EFS/S3
- You autoscale stateless API tiers (EC2 API tuning guide)
- Agentic AI sidecars (tool routers, small models) colocate with app processes
M9gd when:
- Workloads write large temp files (ffmpeg scratch, Spark local dirs, log spools)
- You today pay for provisioned IOPS just to feed ephemeral churn
- You accept data loss on instance stop and design checkpointing to S3
Agentic AI on general-purpose compute
AWS calls out real-time reasoning, code generation, and multi-step orchestration on M9g. That matches what we see in the field: agents are many small CPU bursts (parse tool JSON, call HTTP APIs, render context) chained with variable latency, not one giant GPU job.
Practical placement:
- M9g for agent orchestration planes colocated with existing APIs
- Trainium2/Inferentia2 when inference $/token dominates
- Bedrock when you want managed models. See the June 2026 announcements for Fable 5 and FinOps tooling
Do not resize GPU instances to M9g. Resize everything around the model endpoint.
Migration playbook: M8g → M9g without a Friday outage
Assumes you already run arm64 AMIs or multi-arch containers. If not, complete Graviton migration audit first.
1. Baseline (Day 0)
Export from CloudWatch / APM:
CPUUtilization,CPUCreditBalance(if any burstable mix)- ALB
TargetResponseTimep95 - Cost Explorer filter on
InstanceType = m8g.*
2. Canary (Days 1 to 3)
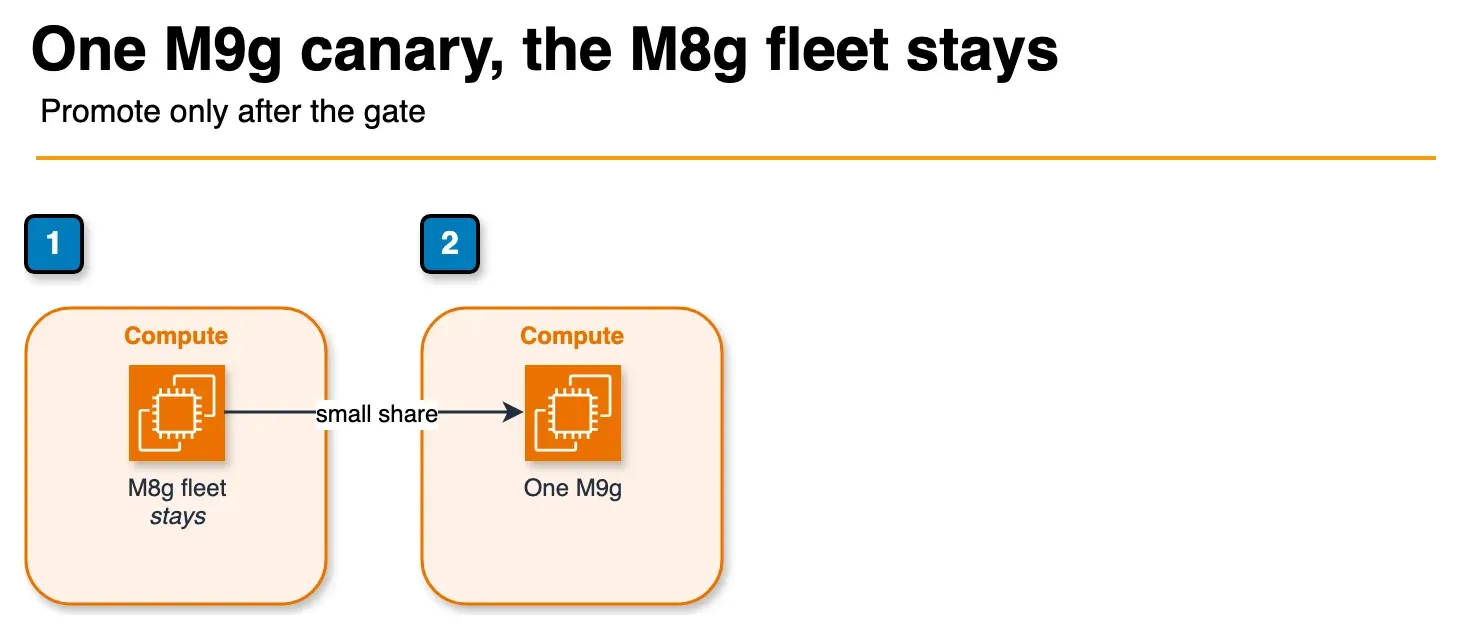
Figure: the canary in the article. The M8g fleet stays up. One matching M9g takes a small share. The article’s weight, the latency rollback rule, and the launch-template promote step stay in the playbook. The checklist files under the other M9g folder were left alone. Open the draw.io source.
- Launch one
m9gmatching yourm8gsize in the same AZ/subnet - Route 5 to 10% target group weight or synthetic load only
- Rollback if p95 > 15% worse at equal CPU
3. Financial gate (Days 4 to 7)
- Compare $/million requests, not just $/hour
- Pause new M8g RI purchases (see the RI vs Savings Plans guide)
- Consider Spot for fault-tolerant batch on M9g (Spot selection guide)
4. Promote (Week 2)
- Update launch template default; keep M8g ASG at 0% min for 48h rollback
- Tag
MigrationWave=m9g-2026for FinOps reporting
M9g vs staying on x86
| Situation | Recommendation |
|---|---|
| Greenfield API on Java 17+ / Node 20+ / Go | M9g after canary |
| Heavy AVX-512 numerical kernels | Benchmark c7i vs c9g when available; do not assume ARM wins |
| Windows workloads | Stay x86 (no Graviton Windows) |
| $100k+/mo EC2 still on m6i/c6i | Run a Graviton TCO project: 5 cost strategies teams overlook |
What This Post Doesn’t Cover
- Per-size vCPU/RAM/network matrix: AWS has not published full instance-size tables in the What’s New post; verify limits in the EC2 instance types documentation before capacity planning.
- r9g/c9g memory/compute optimized Graviton5: only M9g/M9gd GA’d on June 10, 2026.
- Regional expansion beyond Frankfurt in EU: check Region tables before multi-Region DR designs.
- Hands-on benchmark numbers in your account: the pattern above is modeled, not measured on your workloads. Run the canary checklist.
For the broader June launch context (Bedrock, FinOps Agent, Cognito), see the June 2026 AWS roundup.
What to Do This Week
- Inventory all m8g/m8gd ASGs and open RI/SP commitments expiring in the next 90 days.
- Score adoption readiness with the decision matrix: pilot if the sum is 14 or more.
- Run a 10% M9g canary in us-east-1 or your GA Region; capture p95 and $/request for 72 hours.
- Re-evaluate EBS-choked jobs for M9gd, not M9g.
- Tag FinOps on outcomes, and pair it with Cost Explorer monitoring before buying new commitments.
Need help sizing a Graviton5 migration across accounts? FactualMinds runs structured EC2 cost and performance reviews as an AWS Select Tier Services Partner: AWS cost optimization services.
Related reading
- AWS Graviton: The Complete Cost Optimization Guide
- How to Optimize EC2 for High-Performance APIs
- EC2 Spot Instance Intelligent Selection
- AWS Reserved Instances vs Savings Plans (2026)
- AWS Service Announcements: June 2026 Roundup
- AWS Trainium2 and Inferentia2 AI Chips
Frequently asked questions
What are EC2 M9g and M9gd instances?
How much faster is Graviton5 than Graviton4 on M8g?
When should I choose M9gd over M9g?
When should we NOT migrate to M9g yet?
Does M9g support Savings Plans and Spot?
What is the Nitro Isolation Engine on M9g?
Are M9g instances a good fit for agentic AI workloads?
What could go wrong during an M8g to M9g migration?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.